Case analysis. Published
Does a black bar remove the information from a PDF?
The black bar covered it, the PDF kept it
Civio and the PDF Association were the first to write about the text left in this contract's bookmarks. This file downloads the historical copy linked from Civio's article again on 14 October 2026, reads it with two PDF libraries and runs a controlled experiment.
CSINT-CASE-2026-020Open in archive
- What the records show
- The words 870 million Euros, absent from the page text, stand in three bookmark titles of the same file, and all three lead to page 14. Two separate libraries gave the same counts.
- What they do not show
- The text under the black bars. A final total that was paid. Who produced the copy, and by what process.
- Based on
- The DocumentCloud copy linked from Civio: 1,025,010 bytes, SHA-256 beginning 3c79a5de. Downloaded on 14 October 2026 and read locally with PyMuPDF 1.27.2.3 and pypdf 6.10.0.
The record examined
On 29 January 2021 the European Commission published its advance purchase agreement with AstraZeneca with some passages covered by black bars. The same day Civio linked to a copy of the contract. The question is whether text about the covered passages stayed in another part of the file.
Method
The copy was downloaded and its size and SHA-256 recorded. The page text and bookmark titles were read with PyMuPDF 1.27.2.3, and the same counts were repeated with pypdf 6.10.0. The original, a resaved-only control copy and an experiment copy with the bookmark list emptied were then compared on all 41 pages. No file was uploaded to an online service.
Which copy
The file examined is the DocumentCloud copy linked from Civio's article of 29 January 2021. The PDF the Commission publishes today is a separate, different file; it does not stand in for the historical copy.
Recorded SHA-256 values and the download response
logs/preserved-evidence-manifest.json
  "sources\\apa-civio-documentcloud.pdf": "3c79a5dea75766d9efd7d2516927eae16a4211abde70a84ba966a84ba0ecc9d1",
  "sources\\apa_astrazeneca-current.pdf": "08be8ba71d9fd7b9adcdcf02d00bfd58910f4a02e8541989ffbe977d0c7a0ccd",

sources/apa-civio-documentcloud-download.json
  "url": "https://s3.documentcloud.org/documents/20466651/apa_-_astrazenecapdf.pdf",
  "download_utc": "2026-10-14T16:38:43.0531989Z",
  "status": 200,
    "Content-Length": [
      "1025010"
    ],
    "Last-Modified": [
"Fri, 29 Jan 2021 15:05:36 GMT"| Historical copy | Current official PDF | |
|---|---|---|
| Size | 1,025,010 bytes | 3,094,193 bytes |
| SHA-256 begins | 3c79a5de | 08be8ba7 |
| Pages | 41 | 42 |
| Bookmark titles | 254 | 0 |
| Extracted page text | 88,517 characters | 0 characters |
Test 1: the page text
- Pages readObserved
- 41
- Text extractedObserved
- 88,517 characters
- Pages whose text contains 870Observed
- 0
- The byte string 870 in page 14's decompressed content streamObserved
- 0 matches
- Selecting and copying paragraph (b) in the viewerObserved
- 292 characters, no 870
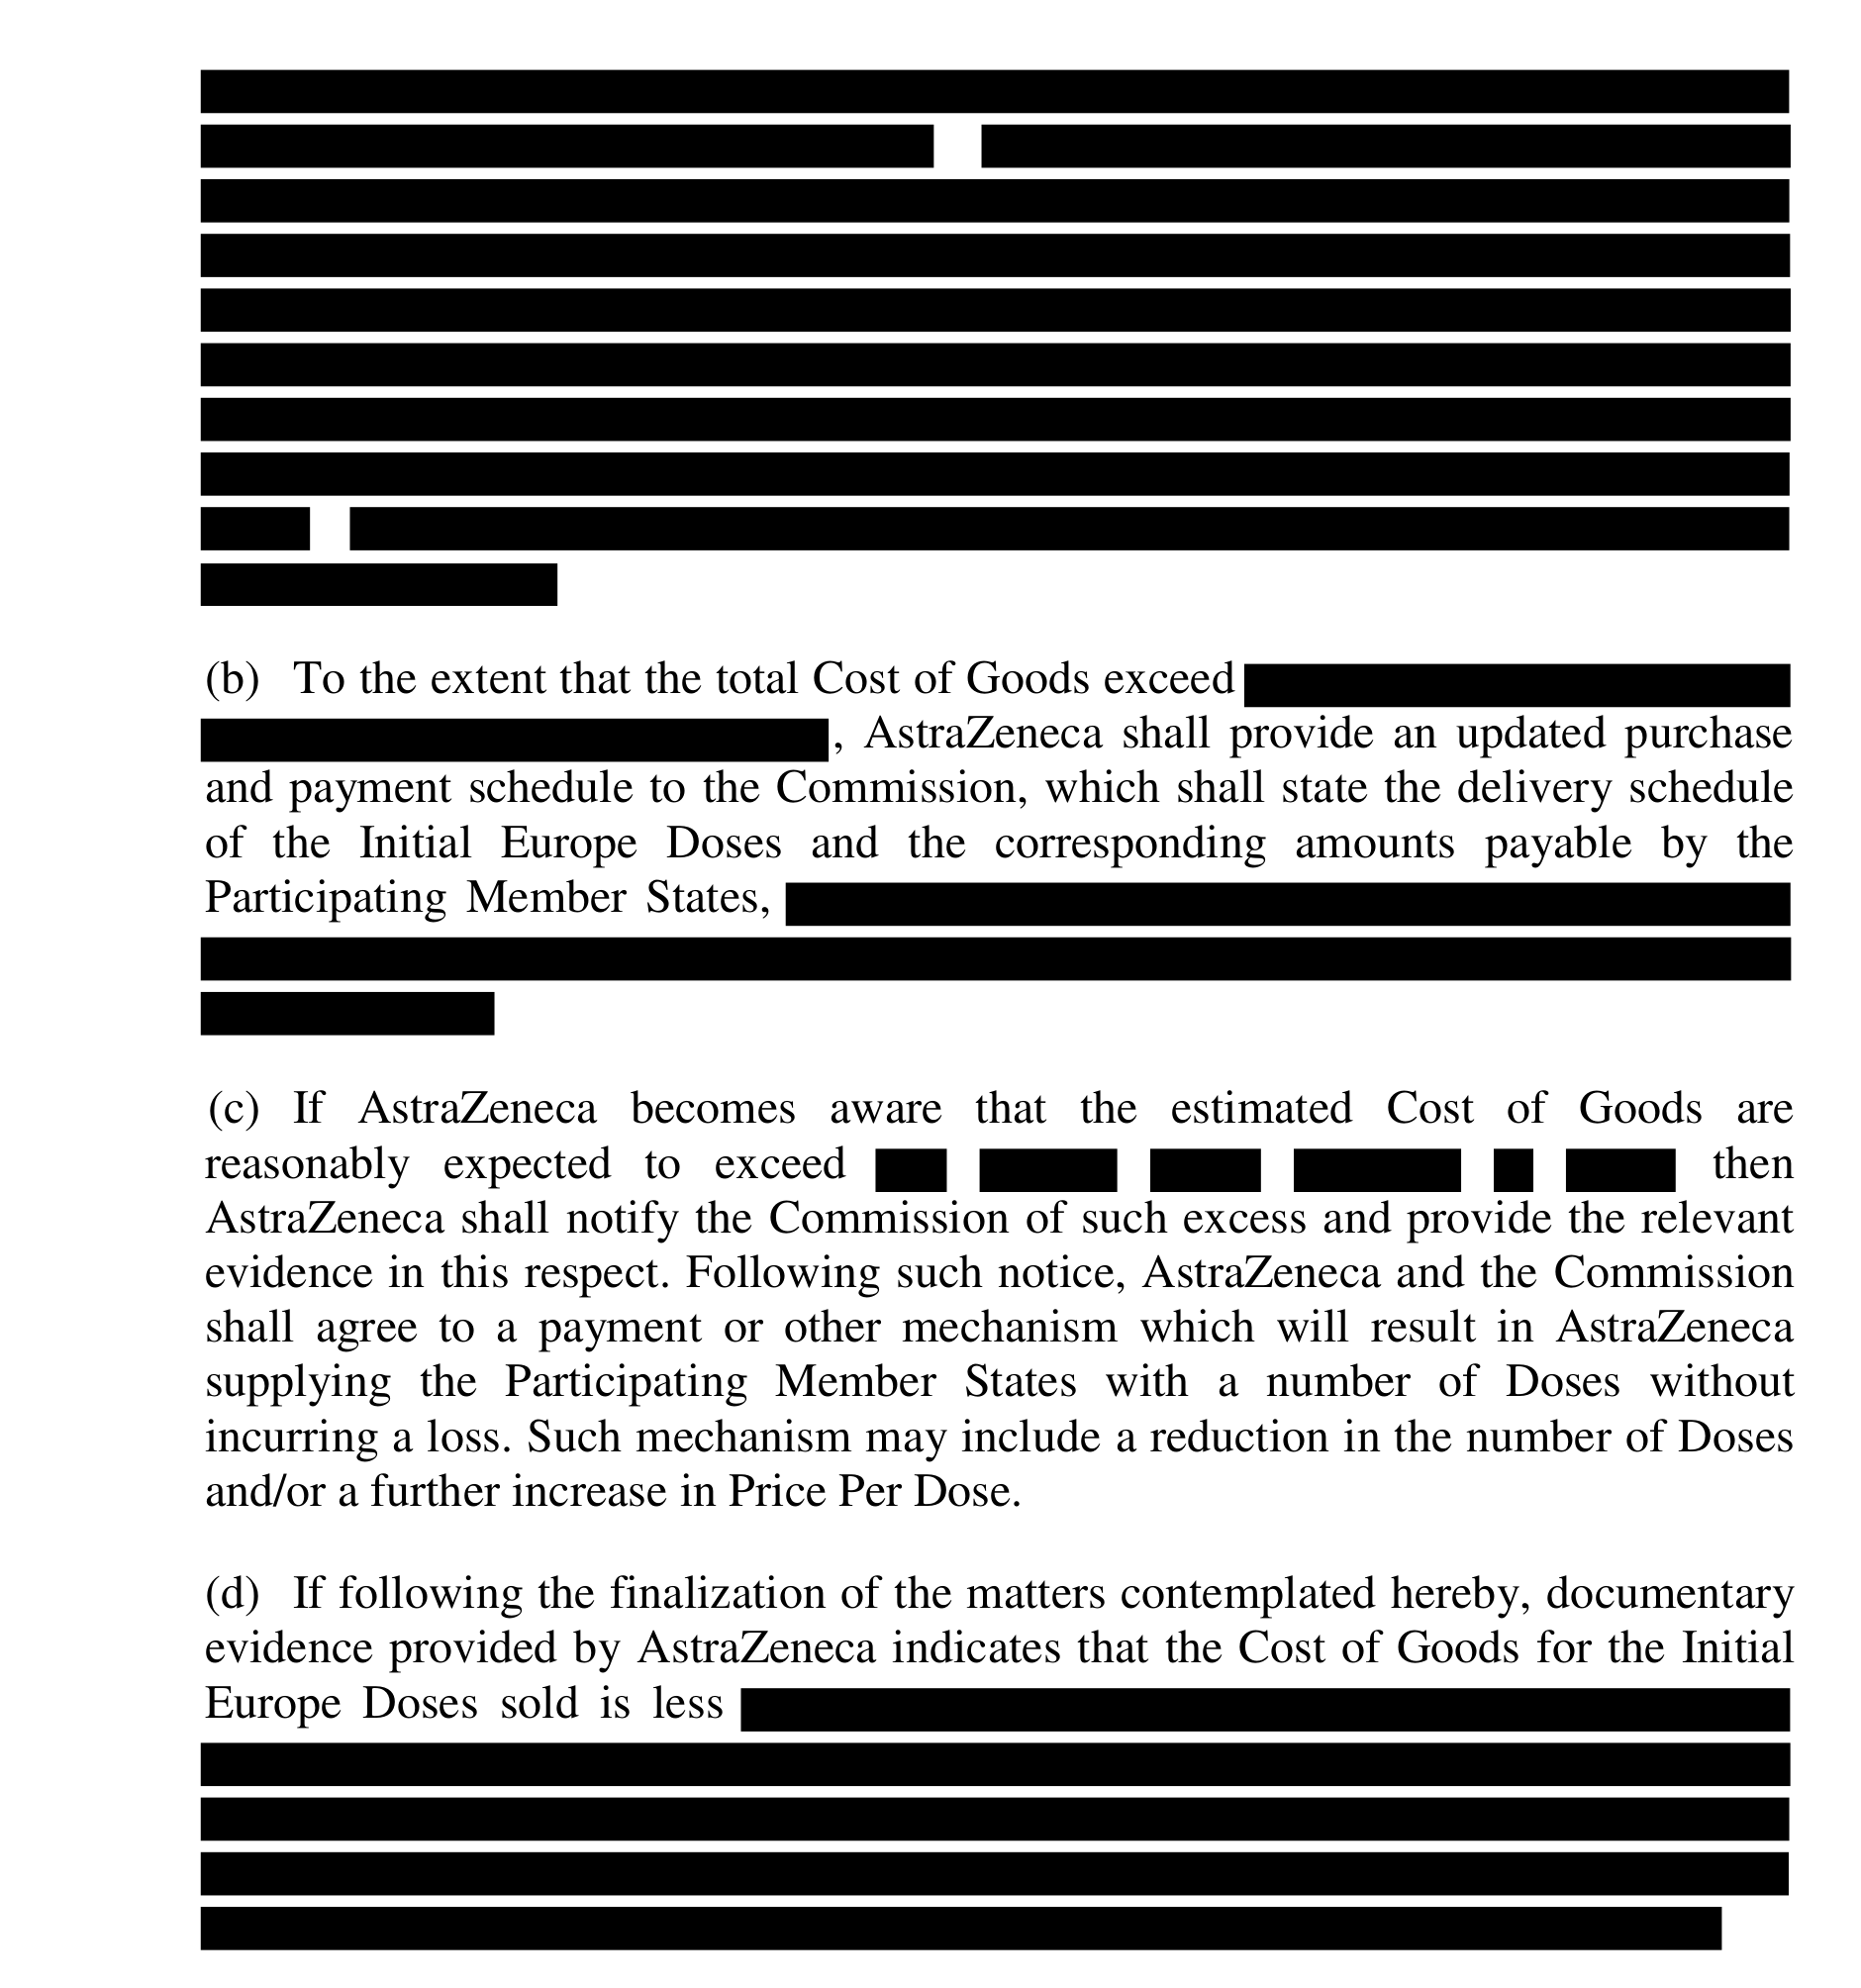
PyMuPDF, text of page 14, lines 16 to 41 (analysis/page14-text.txt)
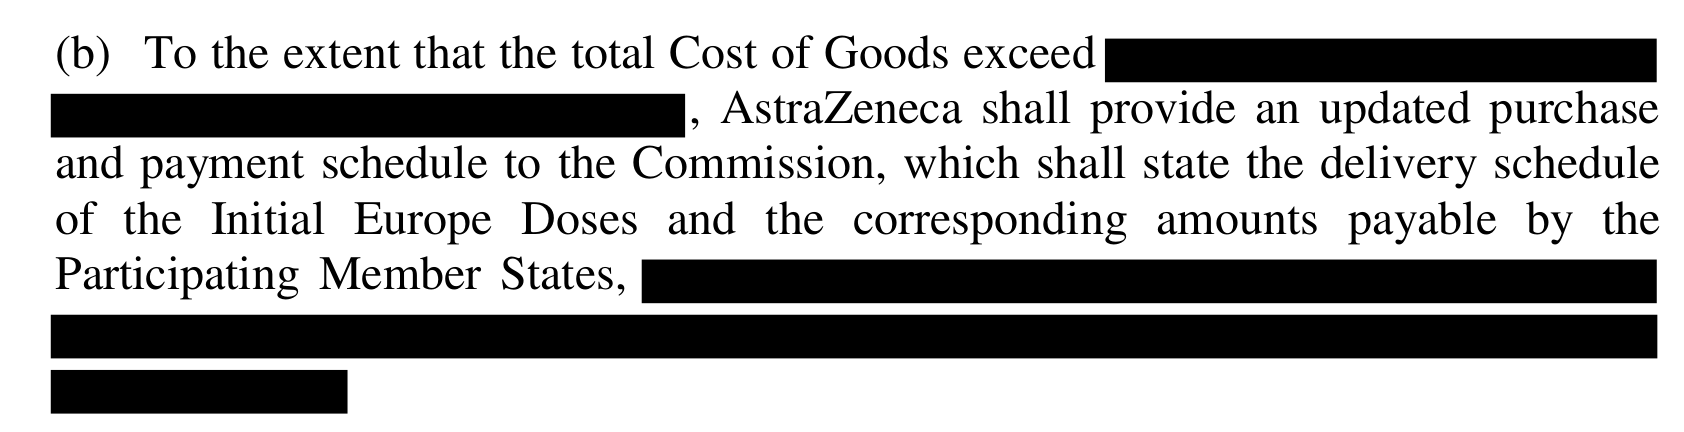
(b) To the extent that the total Cost of Goods exceed

, AstraZeneca shall provide an updated purchase
and payment schedule to the Commission, which shall state the delivery schedule
of the Initial Europe Doses and the corresponding amounts payable by the
Participating Member States,


(c) If AstraZeneca becomes aware that the estimated Cost of Goods are
reasonably expected to exceed


 then
AstraZeneca shall notify the Commission of such excess and provide the relevant
evidence in this respect. Following such notice, AstraZeneca and the Commission
shall agree to a payment or other mechanism which will result in AstraZeneca
supplying the Participating Member States with a number of Doses without
incurring a loss. Such mechanism may include a reduction in the number of Doses
and/or a further increase in Price Per Dose.
(d) If following the finalization of the matters contemplated hereby, documentary
evidence provided by AstraZeneca indicates that the Cost of Goods for the Initial
Europe Doses sold is less Test 2: the bookmarks
Object 465, its /Dest and /Title fields as read with PyMuPDF (analysis/object-465.txt)
<<
  /Dest [ 48 0 R /XYZ 69 599 0 ]
  /Next 464 0 R
  /Parent 457 0 R
  /Prev 458 0 R
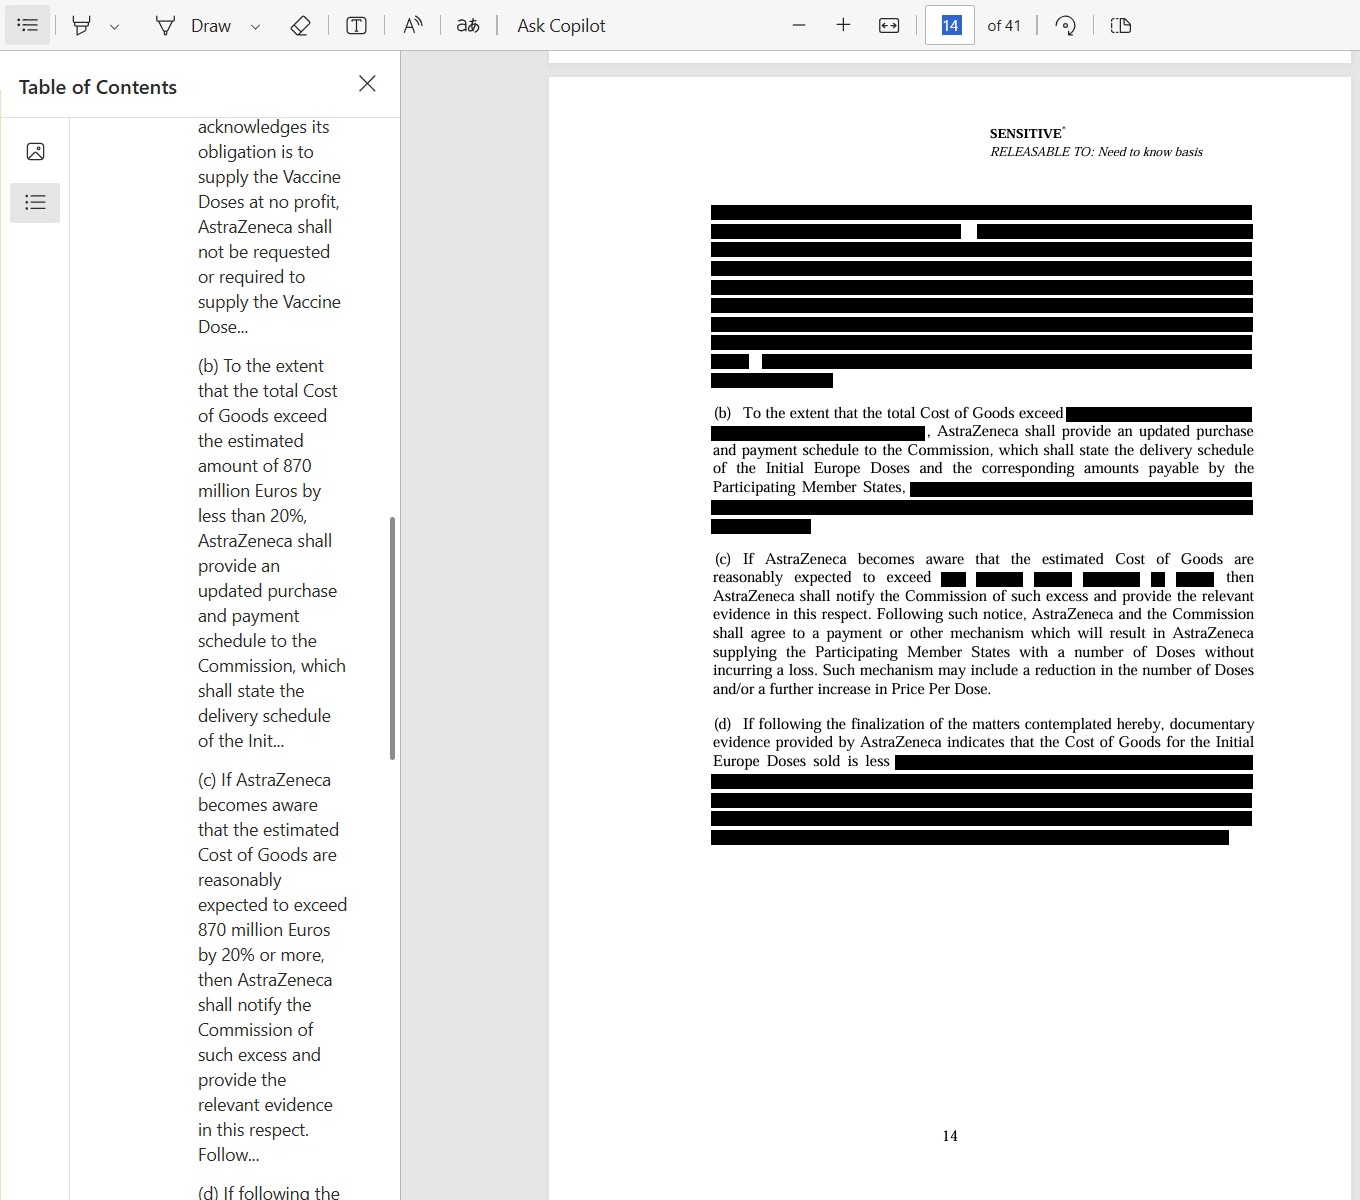
  /Title (\(b\) To the extent that the total Cost of Goods exceed the estimated amount of 870 million Euros by less than 20%, AstraZeneca shall provide an updated purchase and payment schedule to the Commission, which shall state the delivery schedule of the Init...)
>>| Object | Wording in the title | /Dest | Page |
|---|---|---|---|
| 465 | (b) exceed the estimated amount of 870 million Euros by less than 20% | 48 0 R /XYZ 69 599 | 14 |
| 464 | (c) reasonably expected to exceed 870 million Euros by 20% or more | 48 0 R /XYZ 69 490 | 14 |
| 459 | (d) for the Initial Europe Doses sold is less than 870 million Euros | 48 0 R /XYZ 69 368 | 14 |
In the page text, paragraph (b) breaks off at the word exceed and goes on with a comma. The bookmark title that leads to the same paragraph reads the estimated amount of 870 million Euros by less than 20% at that point. This shows the two texts belong to the same paragraph. It does not show exactly what is written under the black bars.
The wording in the bookmark is a condition about an estimated cost. It is not a final total that was paid.
A second library
pypdf 6.10.0, historical copy (analysis/pypdf-verification.json, selected lines)
  "tool": "pypdf",
  "version": "6.10.0",
    "historical": {
      "pages": 41,
      "bookmarks": 254,
          "xref": 465,
          "destination": "[IndirectObject(48, 0, 2501813762624), '/XYZ', 69, 599, 0]"
          "xref": 464,
          "destination": "[IndirectObject(48, 0, 2501813762624), '/XYZ', 69, 490, 0]"
          "xref": 459,
          "destination": "[IndirectObject(48, 0, 2501813762624), '/XYZ', 69, 368, 0]"
      "page_text_870_hits": [],
The two libraries differ on one count: pypdf counts 77 annotations, while PyMuPDF's per-page annotation list is empty. A further check explains it: there are 76 links and 1 form field, and that PyMuPDF list leaves out both kinds. There is no contradiction, but the file cannot be said to have no annotations.
Controlled experiment
Three files were compared. A is the downloaded original, never changed. B is a copy of A only resaved with pypdf. C is a copy of A resaved with its bookmark list removed. B and C were made for this experiment; they are not historical publisher versions.
| A, original | B, resaved | C, list empty | |
|---|---|---|---|
| Pages on reopening | 41 | 41 | 41 |
| Active bookmarks | 254 | 254 | 0 |
| Bookmark titles with 870 | 3 | 3 | 0 |
| Image size, against A | itself | 41/41 same | 41/41 same |
| Raw RGB pixel SHA-256, against A | itself | 41/41 same | 41/41 same |
| Extracted text, against A | itself | 41/41 same | 41/41 same |
| PDF file bytes, against A | itself | different | different |
| Cost-bearing /Title objects | 3: 459, 464, 465 | 3: 550, 551, 552 | 3: 550, 551, 552 |
| Reachable from the file's trailer | yes | yes | no |
The operations behind copy C (analysis/comparison/creation.json)
      "file": "EXPERIMENT-outlines-removed.pdf",
      "role": "experiment: outline deletion plus unreferenced-object cleanup",
      "operations": [
        "clone_document_from_reader(original)",
        "root_object.pop('/Outlines')",
        "compress_identical_objects(remove_duplicates=False, remove_unreferenced=True)",
        "write(new_file)"
      ],
      "bytes": 1107111,
      "sha256": "6bed75bf6cdb11192db05bce7601f14848b1e6c2a9860df85fbc10f9d5b02f37",
      "reopened_pages": 41,
      "catalog_has_outlines": false
Title objects left in copy C, pypdf (analysis/comparison/independent-verification.json)
    "outlines_removed_experiment": {
      "pages": 41,
      "outline_count": 0,
      "page_text_870_count": 0,
      "residual_titles": [
          "xref": 550,
          "title_contains_870": true,
          "reachable_from_trailer": false
          "xref": 551,
          "title_contains_870": true,
          "reachable_from_trailer": false
          "xref": 552,
          "title_contains_870": true,
"reachable_from_trailer": falseWhat to check before sharing
A PDF's page can look clean. The page text, the bookmarks, the document properties and the attachments are separate parts of the file, and each needs its own look. In this copy the wording about the cost was in the bookmarks.
| Part | Read in the historical copy |
|---|---|
| Page text | 41 pages, 88,517 characters, no 870 |
| Bookmarks | 254 titles, three with 870 million Euros |
| Document properties | Title, author, creator, producer and date fields empty; XMP data 0 characters |
| Attachments | 0 |
What we found and what we did not
| Found | Not found |
|---|---|
| No 870 in the page text; 870 million Euros in three bookmark titles. | We did not open the text under the black bars or recover deleted page text. |
| All three titles point to page 14; two libraries gave the same result. | We found no final total that was paid; the wording is a condition about an estimated cost. |
| With the list emptied, the three title objects stayed in the file, detached. | We did not find who produced the copy or by what process. |
What the evidence does not show
- The bookmark wording is a condition about an estimated cost, not a final total that was paid.
- We did not recover deleted page text. We did not open the text under the black areas.
- These measurements do not prove who produced the historical copy or by what process.
- The copy's authenticity depends on a third-party source chain.
- The document was not uploaded to an online service; it was examined locally with PyMuPDF 1.27.2.3 and pypdf 6.10.0.
Working record. Before sharing a PDF, look past the page into the file's other parts. Write down which copy you read.
Video
The video for this file is narrated in Turkish. It is not embedded here; the link opens it on YouTube.Turkish version on YouTube
Sources
- DocumentCloud, apa_-_astrazenecapdf.pdfThe historical copy examined, downloaded on 14 October 2026
- CivioThe article the copy is linked from, 29 January 2021
- PDF Association, Michael KarbeA redaction review of the same contract, 9 February 2021
- European Commission, apa_astrazeneca.pdfThe current official PDF, a separate and different file
- Chris Zabriskie, Cylinder EightMusic in the video, CC BY 4.0. Changes: excerpt, level, fade in and out
Published by Ahmet Göker. Agent and tool contributions shown in the records are listed under Working record. Documents, images and photographs remain with their owners. People are not shown or are blurred.